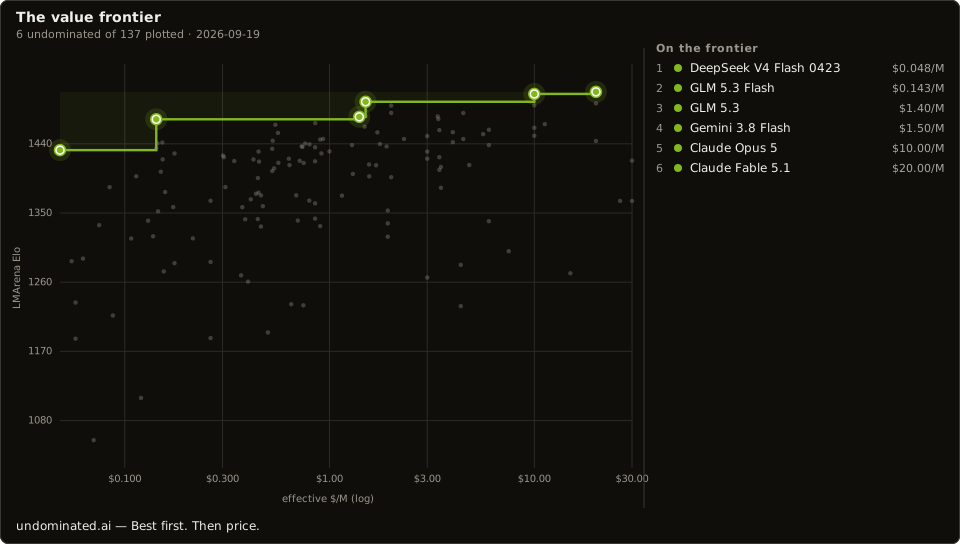
Price × independently measured capability

Compare models

Compare any two or three standard catalogue models, then keep the trade-offs and evidence in a portable decision record.

As of 2026-09-23

Compare · model decision

Choose two or three models

Inspect the differences, estimate your workload and keep the evidence. All standard catalogue models are available, including unrated ones.

Catalogue facts
2026-09-23

0 / 3 selected · 0 requirements
Public workload and requirements

These settings are included in the share link. The fixed-request scenario and private evaluation data below are excluded.

Choose your current model and a candidate, or open a published comparison below.

Keep the decision and its evidence

A portable record retains selected facts, complete tier ladders, public requirements and the publication manifest. It also embeds the full permitted public catalogue to verify the input artifact checksum. Files are larger for this reason (up to 2 MB); local storage is limited to 12 records. Team review is local to this browser; there is no hosted collaboration.

Saving is opt-in and includes private review fields. Shared comparison links never include them. Version 1 Check references remain separate and are not overwritten or guessed into this format.

Saved local decisions · 0

No version 2 decision records are stored in this browser.

Published comparisons

All published model comparisons

50 of 50 comparisons

  1. Claude Fable 5.1 versus Claude Opus 5 Anthropic · Anthropic Editorial comparison · Reasoning and long-workflow choice
  2. Claude Fable 5.1 versus GPT-6 Astra Anthropic · OpenAI Editorial comparison · Cross-provider reasoning shortlist: compare independent scores, context and priced request shapes before a migration.
  3. Claude Opus 4.6 versus MiniMax M2.7 Anthropic · MiniMax Observed search query: “minimax m2.7 vs opus 4.6”
  4. Claude Opus 4.8 versus Claude Opus 5 Anthropic · Anthropic Editorial comparison · Opus migration shortlist: compare exact catalogue versions without assuming tokenizer or endpoint equivalence.
  5. Claude Opus 4.8 versus Kimi K2.6 Anthropic · Moonshot AI Observed search query: “kimi k2.6 vs claude opus 4.8”
  6. Claude Opus 5 versus Claude Sonnet 5 Anthropic · Anthropic Editorial comparison · Tier positioning versus accepted independent evidence
  7. Claude Opus 5 versus Gemini 3.7 Flash Anthropic · Google Operator request: “claude opus 5 vs gemini 3.7 flash”
  8. Claude Opus 5 versus Gemini 3.8 Flash Anthropic · Google Frontier neighbours
  9. Claude Sonnet 4.6 versus gpt-oss-120b Anthropic · OpenAI Observed search query: “gpt oss 120b vs claude sonnet 4.6”
  10. Claude Sonnet 5 versus Gemini 3.8 Flash Anthropic · Google Editorial comparison · Cross-provider application shortlist: inspect modality, output and cache differences at the same stated workload.
  11. Claude Sonnet 5 versus GPT-5.6 Sol Anthropic · OpenAI Operator request: “gpt 5.6 sol vs claude sonnet 5”
  12. Command A versus Command R+ (08-2024) Cohere · Cohere Editorial comparison · Both vendor-live; evaluate RAG/tool workload
  13. DeepSeek V4 Flash 0423 versus Gemma 4 26B A4B DeepSeek · Google Operator request: “deepseek v4 flash vs gemma 4 26b”
  14. DeepSeek V4 Flash 0423 versus Nemotron 3 Super DeepSeek · NVIDIA Observed search query: “nemotron 3 super vs deepseek v4 flash”
  15. DeepSeek V4 Flash 0423 versus Qwen3 30B A3B Instruct 2507 DeepSeek · Qwen Frontier neighbours
  16. DeepSeek V4 Pro 0813 versus DeepSeek V4.1 Flash DeepSeek · DeepSeek Editorial comparison · Alias and modality caveat required
  17. DeepSeek V4.1 Flash versus Kimi K3 DeepSeek · Moonshot AI Editorial comparison · Long-context application shortlist: compare the full context ladder and time-dependent billing caveats.
  18. Gemini 2.5 Flash Lite versus Gemini 3.5 Flash Lite Google · Google Editorial comparison · Generation migration; direct Gemini 2.5 access restriction matters
  19. Gemini 3.1 Pro Preview versus Gemini 3.8 Flash Google · Google Editorial comparison · Stable Flash versus preview Pro
  20. Gemini 3.7 Flash versus Gemini 3.8 Flash Google · Google Editorial comparison · Adjacent stable Flash releases
  21. Gemini 3.7 Flash versus GPT-5.6 Sol Google · OpenAI Operator request: “gpt 5.6 sol vs gemini 3.7 flash”
  22. Gemini 3.8 Flash versus GLM 5.3 Google · Z.ai Frontier neighbours
  23. Gemma 3 12B versus Gemma 3 4B Google · Google Frontier neighbours
  24. Gemma 3 12B versus Qwen3 30B A3B Instruct 2507 Google · Qwen Frontier neighbours
  25. Gemma 3 4B versus gpt-oss-20b Google · OpenAI Frontier neighbours
  26. Gemma 4 26B A4B versus Gemma 4 31B Google · Google Editorial comparison · MoE versus dense; do not substitute active size for model memory
  27. Gemma 4 26B A4B versus Hy3 Google · Tencent Frontier neighbours
  28. Gemma 4 31B versus GLM 5.3 Flash Google · Z.ai Frontier neighbours
  29. Gemma 4 31B versus Hy3 Google · Tencent Frontier neighbours
  30. Gemma 4 31B versus MiMo-V2.5-Pro Google · Xiaomi Operator request: “gemma 4 31b vs mimo v2.5 pro”
  31. GLM 5.3 versus GLM 5.3 Flash Z.ai · Z.ai Editorial comparison · Text main checkpoint versus multimodal Flash
  32. GLM 5.3 Flash versus GLM 5.3 FlashX Z.ai · Z.ai Editorial comparison · Serving-labelled variants; no measured latency claim
  33. GPT-5.4 Mini versus GPT-5.4 Nano OpenAI · OpenAI Editorial comparison · Small-model choice without assumed capabilities
  34. GPT-5.6 Luna versus GPT-5.6 Terra OpenAI · OpenAI Editorial comparison · Cost-sensitive same-generation choice
  35. GPT-5.6 Sol versus GPT-5.6 Terra OpenAI · OpenAI Editorial comparison · Same generation; independent named model rows
  36. GPT-5.6 Sol versus GPT-6 Astra OpenAI · OpenAI Editorial comparison · Named-model generation change; preserve Pro/mode distinctions
  37. GPT-6 Astra versus Grok 4.7 OpenAI · xAI Editorial comparison · Cross-provider reasoning shortlist: retain uncertainty and endpoint checks alongside measured quality.
  38. Grok 4.6 versus Grok 4.7 xAI · xAI Editorial comparison · Recent reasoning versions
  39. Kimi K2.6 versus Kimi K3 Moonshot AI · Moonshot AI Editorial comparison · Generation change and preserved-thinking contract
  40. Llama 4 Maverick versus Llama 4 Scout Meta · Meta Editorial comparison · Distinct official multimodal checkpoints
  41. MiniMax M2.7 versus MiniMax M3 MiniMax · MiniMax Editorial comparison · Modality and reasoning change; licence caution
  42. MiniMax M3 versus GLM 5.3 MiniMax · Z.ai Editorial comparison · Cross-provider agent shortlist: tool support alone does not establish equivalent task success.
  43. Ministral 3 14B 2512 versus Ministral 3 8B 2512 Mistral · Mistral Editorial comparison · Same generation, distinct checkpoints
  44. Muse Spark 1.2 versus Muse Spark 1.2 Contributor Meta · Meta Observed search query: “muse spark 1.2 vs muse spark 1.2 contributor”
  45. Nova Lite 1.0 versus Nova Micro 1.0 Amazon · Amazon Editorial comparison · Text-only versus multimodal is an explicit trade-off
  46. o3 versus o3 Pro OpenAI · OpenAI Editorial comparison · Base versus Pro; independent score required
  47. Qwen3 235B A22B Instruct 2507 versus Qwen3 235B A22B Thinking 2507 Qwen · Qwen Editorial comparison · Separate Instruct and Thinking checkpoints
  48. Qwen3 VL 30B A3B Instruct versus Qwen3 VL 30B A3B Thinking Qwen · Qwen Editorial comparison · Same size label, different checkpoint and evaluation
  49. Qwen3.6 27B versus Qwen3.8 27B Qwen · Qwen Editorial comparison · Exact dense model revisions
  50. Step 3.5 Flash versus Step 3.7 Flash StepFun · StepFun Editorial comparison · Modality difference; newer unrated row stays unrated
Evidence & Ask