Choose the task. Inspect the evidence.
AI rankings by model type
Language, vision, music and retrieval need different measurements. Each board below keeps its own models, metric and source date. There is no combined “best AI” score.
Source publication dates can be older than the retrieval date. “Checked” means the source was retrieved, not that it published a new measurement.
Language models
Coding and agents
Search and documents
Vision
Images
Video
Music
Rerankers
Embeddings
The embedding comparison uses the accepted MTEB (English, v2) task set. Complete benchmark coverage and partial results remain distinguishable; unmeasured tasks are never counted as zero.
Explore embedding rankings and prices →Speech and audio
Official boards are available. Their scores are not yet imported here because a reusable result snapshot has not been verified.
Speech recognition
Word error rate; lower is better.
Read the current results on the official versioned board. Compare the same language and test sets; these scores are not imported into Undominated.
Open Hugging Face Open ASR Leaderboard ↗Speech generation
Speech intelligibility, voice similarity and speed.
Read the current results on the official board. These objective metrics measure different properties; they are not a single human preference score. Scores are not imported here.
Open Hugging Face Open TTS Leaderboard ↗Compare scores and prices
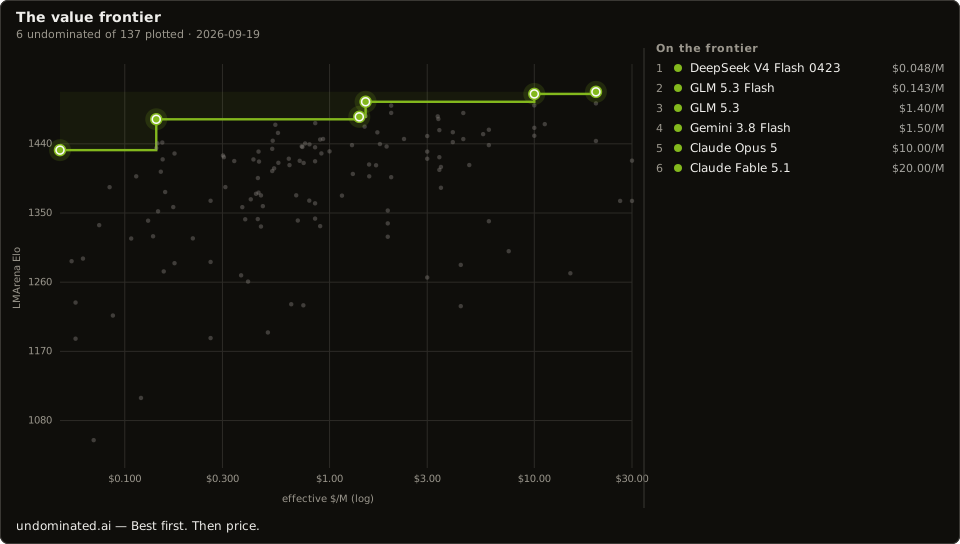
Benchmark coverage and purchasable API coverage differ. These comparison pages match available measurements with source-backed prices.
Explore language-model task rankings and Design Arena results →
Language models and task rankings →
Capability, uncertainty, provider offers and workload prices.
Image models →
Independent scores alongside available prices and their conditions.
Video models →
Independent scores alongside available prices and their conditions.
Embedding models →
Independent scores alongside available prices and their conditions.
Read a rank carefully
Where confidence bounds are published, ranks count models whose intervals clearly exceed another model’s interval. Where bounds are absent, ranks order point estimates only. A missing score is never zero.