Choose the evidence
Which benchmark answers your question?
Start with the job your system must do. Preference, retrieval, issue resolution and tool use measure different outcomes. Keep their scores separate, then test your shortlist on your own acceptance criteria.
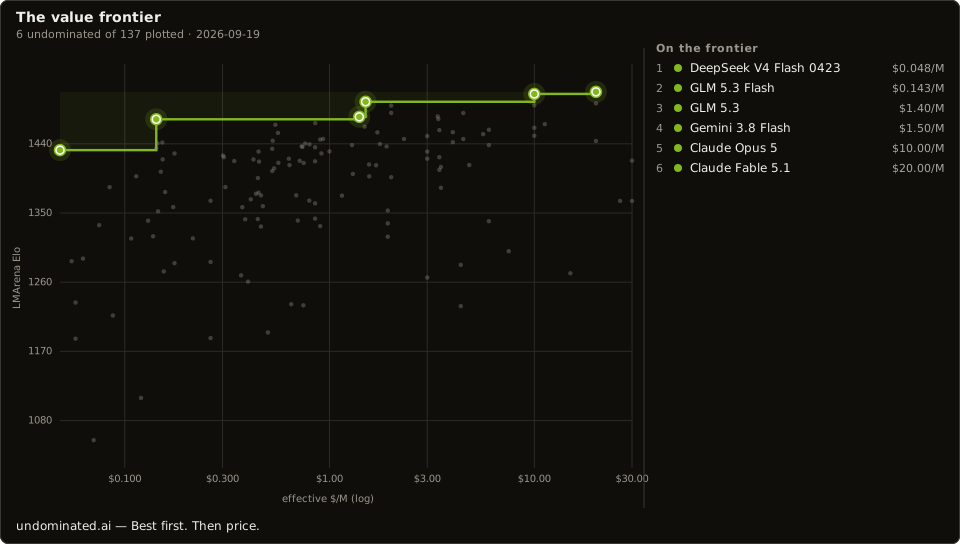
Compare conversational preference within a published task
Arena human preference
Use preference ratings to form a shortlist, then inspect uncertainty and the exact model variant before comparing cost.
136 / 346 standard model entries have an accepted Arena score. Catalogue as of 2026-09-23.
Inspect measurement and limitations →Choose embeddings for retrieval and related representation tasks
MTEB embedding evaluation
An embedding average is useful only when its task collection, aggregation and model revision are clear. Retrieval quality still needs a corpus-specific check.
20 / 57 embedding entries have a complete accepted benchmark score. Catalogue as of 2026-09-23.
Inspect measurement and limitations →Evaluate repository issue resolution
SWE-bench coding agents
A coding result describes a model working through a particular agent and environment. Compare the full run configuration before treating a leaderboard entry as a model choice.
Method guide with links to the official results. Scores from this benchmark are not ingested into Undominated.
Inspect measurement and limitations →Evaluate agents operating in terminal environments
Terminal-Bench agent tasks
Terminal results depend on the task environment as well as the model. Pin the environment and verifier when comparing systems or repeating a result.
Method guide with links to the official results. Scores from this benchmark are not ingested into Undominated.
Inspect measurement and limitations →Evaluate structured tool use and agentic interactions
Berkeley Function Calling Leaderboard
Tool-call correctness is more specific than general chat quality. Check the evaluation category and whether the model uses native function calling or a prompting workaround.
Method guide with links to the official results. Scores from this benchmark are not ingested into Undominated.
Inspect measurement and limitations →Turn a leaderboard into a decision
- Choose the task and define an acceptable result.
- Match benchmark version, model variant, tools and budget.
- Keep cost, latency, correctness and failure recovery as separate observations.
- Compare your shortlist, attach private evaluation results, and save a record of the evidence used.
Guide sources reviewed 2026-09-23. Coverage counts come from the accepted catalogue; they are not a census of every public result.