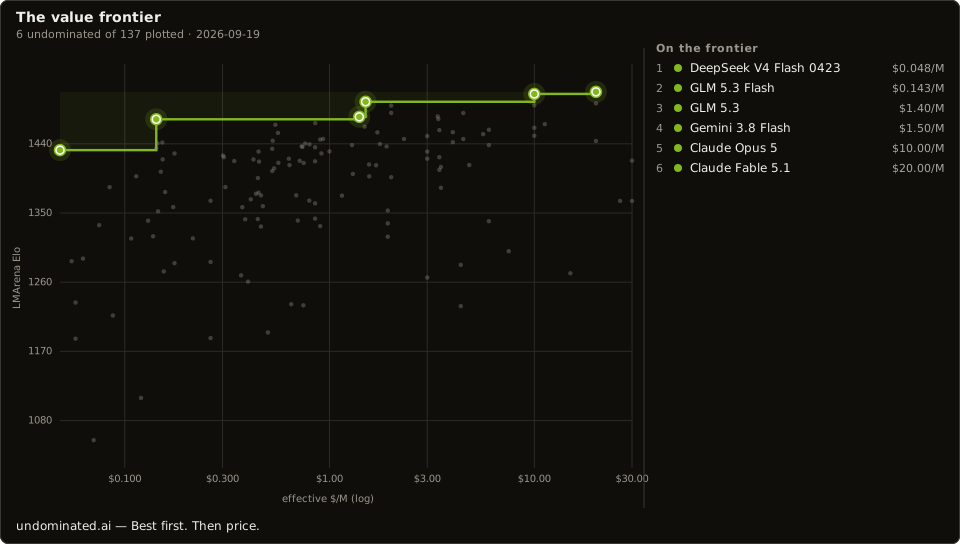
Compare conversational preference within a published task
Arena human preference
Use preference ratings to form a shortlist, then inspect uncertainty and the exact model variant before comparing cost.
Source reviewed 2026-09-23 · Official Arena leaderboard dataset
What it measures
Pairwise human preferences produce task-specific ratings and published confidence bounds. A rating belongs to its board, model identity and observation period.
Undominated publishes a scoped set of accepted results; see the linked instrument for its exact task, date and coverage.
What the result does not establish
- Preference is not a measurement of your application’s correctness, reliability or operating cost.
- A text rating and an image-edit rating do not share a frontier. Neither does a model automatically inherit another variant’s result.
- Overlapping intervals make a rigid ordering harder to justify. Inspect the significance view before interpreting small displayed gaps.
Hold these conditions constant
- Same benchmark task and published snapshot
- Exact version and reasoning configuration
- Published confidence interval and observation coverage
- Application constraints such as tools, context and input modalities
An evaluation for your team
Run the shortlisted models on the same representative prompts with blinded review. Define acceptable answers before scoring; separately record attempts, accepted results, observed cost and latency.
Write down the task version, attempt count, accepted outcomes, observed spend and latency. Preserve failures in the denominator. A new model version or tool configuration deserves a new record.
Editorial guidance is not a new measurement. Follow the official source for its current benchmark definition and result history.