
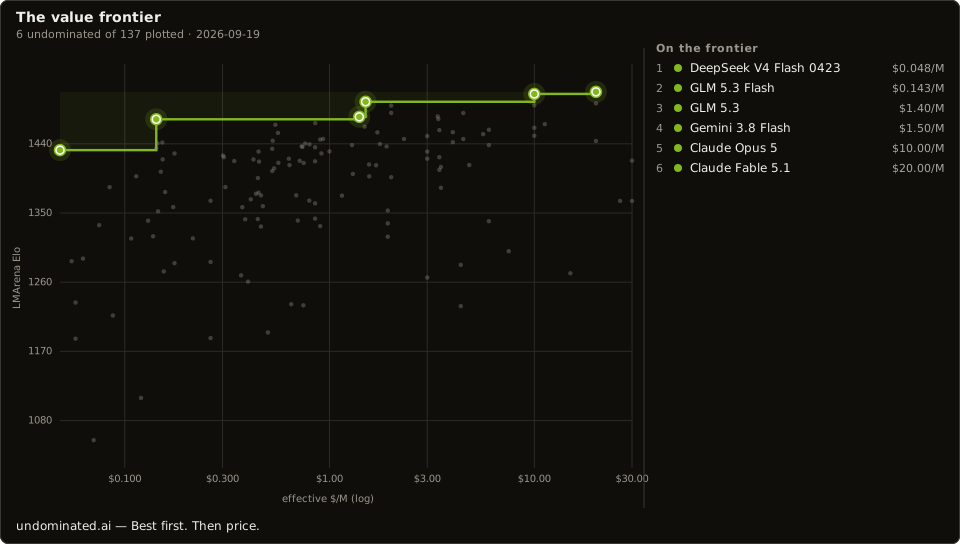
MODEL PROOF
Claude Opus 5
FRONTIER
Nothing is both better and cheaper under this workload.
- Independent LMArena score
- 1,504.9 ± 4.22 · 42,617 votes
- Context window
- 1M
- Maximum output
- 128K
- Input modalities
- text, image, file
- Output modalities
- text
- Published input price
- $5.00 / 1M tokens
- Published output price
- $25.00 / 1M tokens
- Pricing kind
- fixed
Inspect complete billing conditions and endpoint terms below.
Every price dimension · USD per million tokens
| Input | $5.00/M |
|---|---|
| Output | $25.00/M |
| Cached input | $0.500/M |
| Cache write | $6.25/M |
| Cache write 1h | $10.00/M |
| Reasoning | Unknown/M |
| Web search | $0.01/call |
| Batch discount | 50% |
Who sells it
The same weights, different shops. Cheapest is not like-for-like when serving precision differs.
11 provider offers · rates, limits and conditions
Rates are USD per million tokens. Endpoint terms can differ even when the quoted price and precision match. A listed parameter is a provider declaration, not a task-success test.
| Seller | Input | Output | Precision | Uptime (1d) |
|---|---|---|---|---|
| Claude Platform on AWSclaude-on-aws Endpoint terms
| $5.00 | $25.00 | undeclared | 99.98% |
| Googlegoogle-vertex/global Endpoint terms
| $5.00 | $25.00 | undeclared | 99.94% |
| Amazon Bedrockamazon-bedrock Endpoint terms
| $5.00 | $25.00 | undeclared | 99.94% |
| Azureazure/global Endpoint terms
| $5.00 | $25.00 | undeclared | 99.98% |
| Anthropicanthropic Endpoint terms
| $5.00 | $25.00 | undeclared | 99.98% |
| Amazon Bedrockamazon-bedrock/eu-west-1 Endpoint terms
| $5.50 | $27.50 | undeclared | 99.92% |
| Azureazure/us Endpoint terms
| $5.50 | $27.50 | undeclared | — |
| Googlegoogle-vertex/us Endpoint terms
| $5.50 | $27.50 | undeclared | — |
| Googlegoogle-vertex/europe Endpoint terms
| $5.50 | $27.50 | undeclared | 100.00% |
| Amazon Bedrockamazon-bedrock/us-east-1 Endpoint terms
| $5.50 | $27.50 | undeclared | 100.00% |
| Anthropicanthropic/fast Endpoint terms
| $10.00 | $50.00 | undeclared | 100.00% |
Independent scores
| LMArena Elo | 1504.9high |
|---|
LMArena Elo under CC BY 4.0. Absence of another board is not a score of zero.
Best rankings by task
- asciiart #1of 61 1372
- mobileapps #1of 40 1348
- godotgamedev #2of 30 1275
- agenticgamedev #2of 24 1261
- uicomponent #3of 104 1359
- svg #3of 76 1340
- androidnative #3of 35 1270
- codecategories #4of 108 1332
Capability
| Context window | 1M |
|---|---|
| Max output | 128K |
| Input modes | text, image, file |
| Tool use | yes |
| Reasoning | optional |
| Open weights | no |
Provenance
| Price source | openrouter.ai |
|---|---|
| Fetched | 2026-09-23 |
| Quality data | verified |
| Cross-checked | vendor page |
A published time-to-first-token figure for this model was implausible (41s) and has been withheld rather than displayed.
Our take
editorial — not a measurementOpus is a candidate for complex coding and document workflows, but its fit depends on your task evaluations and reasoning settings. Compare the current proof with the alternatives before treating it as a default. Inspect cache, batch and delivery-mode terms separately. The suspect latency figure is withheld, so measure latency before an interactive deployment.
Strengths
- Tool use, structured outputs and selectable reasoning effort are listed
- Cache and batch options can be assessed against repeated-context workloads
Weaknesses
- Token counts can differ across tokenizers even for identical text
- A delivery-mode label does not establish a measured latency advantage
Reach for it when
- Evaluation for complex coding tasks
- Document workflows with repeated context
Avoid it if
- You require untested interactive latency
- A simpler model already meets your task requirements
Claude Opus 5 is Anthropic’s flagship model for demanding reasoning, coding, and long-horizon agentic work. It is particularly strong at end-to-end software tasks, code review and bug finding, visual analysis...
Questions this page answers
What does Claude Opus 5 cost?
$5.00/M in, $25.00/M out in this catalogue, as of the fetch date on this page. That is the API row, not a subscription.
Does Claude Opus 5 have an independent quality score?
Claude Opus 5 has an LMArena score in this catalogue.
What beats Claude Opus 5?
Nothing is both better and cheaper than Claude Opus 5.
Does this page use Artificial Analysis scores for Claude Opus 5?
No. Artificial Analysis figures are not published here. Quality on this page is LMArena Elo where a score exists; otherwise the row is unrated.
MODEL MONUMENT
Save or share this proof
Badge
The verdict as one SVG, for a README or a docs page. It states this model's dominance status at the balanced workload on the LMArena lens, with the date it was computed, and it is rebuilt with the catalogue — so it changes when the verdict changes, including to one you would rather it did not.
[](https://undominated.ai/models/anthropic__claude-opus-5/)<a href="https://undominated.ai/models/anthropic__claude-opus-5/"><img src="https://undominated.ai/badge/anthropic__claude-opus-5.svg" alt="Claude Opus 5 — Undominated.ai dominance verdict" height="36"></a>Direct file: https://undominated.ai/badge/anthropic__claude-opus-5.svg — a static SVG, written by scripts/build-badges.mjs on every build, so the copy you embed is never
older than the last deploy.
