Alternatives to GPT-6 Astra
OpenAI LMArena 1441.2 $20.00/M on a balanced workload prices as of 2026-11-05, except 8 under confirmation
5 models are higher-scoring or cheaper, with neither dimension worse.
Of the 141 models carrying both an independent score and a published price at the same delivery mode, 45 score at least as high as GPT-6 Astra and cost no more under at least one listed workload, with at least one of those dimensions improved. 44 of them cost less; the rest match the price and have a higher score. 5 match or beat its recorded context, maximum output, input modes, tool use and extended reasoning. 40 have a recorded capability loss, named on every row.
Dominance is not a property of a model. It is a property of a model, a capability lens and a workload, and all three are named on every row. Scores are LMArena Elo, used under CC BY 4.0 from the official dataset; prices are blended per million tokens. A higher score is not a drop-in replacement.
This page lists models only while a candidate improves score or price without worsening the other under a listed workload. When that comparison no longer holds, this address stays and says so.
Where it holds
| Workload | GPT-6 Astra $/M | Recorded capabilities preserved | Recorded capability losses |
|---|---|---|---|
| Balanced | $20.00 | 5 | 40 |
| Summarise | $9.44 | 5 | 40 |
| Chat | $23.30 | 5 | 40 |
| Code gen | $33.28 | 5 | 40 |
| Agentic | $10.65 | 5 | 40 |
Workload mixes are defined on the methodology page. Cached input is priced at the cached rate, and reasoning tokens at the worse of the reasoning and output rates.
What you would be replacing
| Intelligence | 1441.2 |
|---|---|
| Context window | 1M |
| Max output | 128K |
| Input modes | file, image, text |
| Tool use | yes |
| Extended reasoning | yes |
Preserving recorded capabilities requires matching or beating these fields. Full record for GPT-6 Astra, or check GPT-6 Astra against the whole catalogue.
Recorded capabilities preserved 5
Each option has a higher score or a lower price, with neither dimension worse under the listed workloads. It matches or beats GPT-6 Astra on recorded context, maximum output, input modes, tool use and extended reasoning.
| # | Model | Intelligence | $/M | Holds under |
|---|---|---|---|---|
| 1 | GPT-5.5 OpenAI | 1466.8 +25.6 | $11.25 |
|
| 2 | GPT-5.6 Sol OpenAI | 1457.2 +16 | $8.00 |
|
| 3 | GPT-5.4 OpenAI | 1452.5 +11.3 | $5.63 |
|
| 4 | GPT-5.6 Terra OpenAI | 1448.3 tie | $4.50 |
|
| 5 | GPT-6.1 Sol OpenAI | 1445.6 tie | $4.00 |
|
Alternatives with recorded capability losses 40
These improve score or price without worsening the other under the listed workloads, but reduce at least one recorded capability. Read the last column before switching.
| Model | Intelligence | $/M | Holds under | Recorded capability loss |
|---|---|---|---|---|
| Gemini 4 Argon Google | 1528.6 +87.4 | $8.00 |
|
|
| Claude Opus 5.5 Anthropic | 1515.8 +74.6 | $8.00 |
|
|
| Claude Fable 5.1 Anthropic | 1513.8 +72.6 | $20.00 |
|
|
| Claude Opus 5 Anthropic | 1504.1 +62.9 | $10.00 |
|
|
| Gemini 3.8 Flash Google | 1498.5 +57.3 | $3.00 |
|
|
| Claude Opus 4.6 Anthropic | 1501.7 +60.5 | $10.00 |
|
|
| Muse Wonder Meta | 1499.2 +58 | $8.00 |
|
|
| MiMo-V2.6-Pro Xiaomi | 1491.4 +50.2 | $0.540 Price under confirmation since Nov 5, 2026 |
|
|
| Muse Spark 1.3 Meta | 1490.6 +49.4 | $2.00 |
|
|
| Gemini 3.7 Flash Google | 1489.1 +47.9 | $3.00 |
|
|
| Claude Opus 4.7 Anthropic | 1489.7 +48.5 | $10.00 |
|
|
| Muse Spark 1.2 Meta | 1482.7 +41.5 | $2.00 |
|
|
| Claude Fable 5 Anthropic | 1491.6 +50.4 | $20.00 |
|
|
| Gemini 3.6 Flash Google | 1479.8 +38.6 | $1.50 |
|
|
| Gemini 3.1 Pro Preview Google | 1480.1 +38.9 | $4.50 |
|
|
| Muse Spark 1.1 Meta | 1478.3 +37.1 | $2.00 |
|
|
| Gemini 3.5 Flash Google | 1478.2 +37 | $3.38 |
|
|
| Kimi K3 Moonshot AI | 1475.7 +34.5 | $3.96 Price under confirmation since Nov 4, 2026 |
|
|
| GLM 5.3 Z.ai | 1473.8 +32.6 | $0.409 Price under confirmation since Nov 4, 2026 |
|
|
| GLM 5.3 Flash Z.ai | 1473 +31.8 | $0.102 Price under confirmation since Nov 5, 2026 |
|
|
| Claude Sonnet 5.5 Anthropic | 1472.9 +31.7 | $4.00 |
|
|
| GLM 5.2 Z.ai | 1469.6 +28.4 | $0.409 Price under confirmation since Nov 4, 2026 |
|
|
| DeepSeek V4.1 Flash DeepSeek | 1464.5 +23.3 | $0.096 Price under confirmation since Nov 5, 2026 |
|
|
| MiMo-V2.5-Pro Xiaomi | 1464.2 +23 | $0.810 Price under confirmation since Nov 5, 2026 262K context at this price; 1M published |
|
|
| GLM 5.1 Z.ai | 1462.8 +21.6 | $1.40 |
|
|
| Claude Opus 4.8 Anthropic | 1461.3 +20.1 | $10.00 |
|
|
| Gemini 2.5 Pro Google | 1457.7 +16.5 | $3.44 |
|
|
| Kimi K2.6 Moonshot AI | 1455.6 +14.4 | $1.40 |
|
|
| Claude Sonnet 4.6 Anthropic | 1457.7 +16.5 | $6.00 |
|
|
| Qwen3.7 Plus Qwen | 1454.6 +13.4 | $0.560 |
|
|
| MiMo-V2.6-Flash Xiaomi | 1451.2 tie | $0.175 |
|
|
| Grok 4.5 xAI | 1447.6 tie | $3.00 |
|
|
| Claude Opus 4.5 Anthropic | 1450.9 tie | $10.00 |
|
|
| GLM 5 Z.ai | 1445.9 tie | $1.09 |
|
|
| DeepSeek V4 Pro 0423 DeepSeek | 1446 tie | $1.53 |
|
|
| Kimi K2.5 Moonshot AI | 1444.9 tie | $1.20 |
|
|
| Gemma 4 31B Google | 1443 tie | $0.205 Price under confirmation since Nov 4, 2026 |
|
|
| Step 5 Preview StepFun | 1442.7 tie | $1.43 |
|
|
| Inkling Thinking Machines | 1442.7 tie | $1.76 |
|
|
| Claude Sonnet 5 Anthropic | 1442.7 tie | $4.00 |
|
|
What this compares, and what it leaves out
- Quality is LMArena Elo, used under CC BY 4.0 from the official dataset. The 95% confidence interval on a difference between two scores is about ±10.21 points, so a gap smaller than that is marked tie rather than an improvement — see significance bands.
- 197 further models at this delivery mode carry a price but no independent score. They are absent from the comparison in both directions — unrated is not a zero, and an unmeasured model is neither an alternative nor a worse buy.
- Retired models are never offered as an alternative, and a model only competes against its own delivery mode: batch trades latency for price, so it is not a like-for-like swap.
- Nothing here measures latency, throughput, rate limits or how a model behaves on your prompts. Two models with the same index score are not interchangeable.
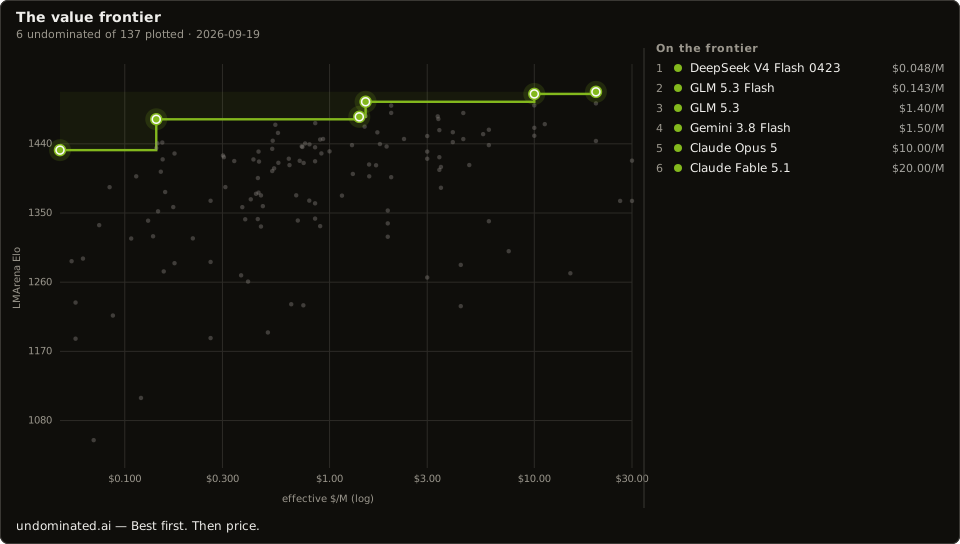
- Models with no higher-scoring or cheaper alternative that is no worse on the other axis are on the value frontier. Models with such an alternative are listed here.