Alternatives to GLM 5V Turbo
Z.ai LMArena 1437.2 $1.90/M on a balanced workload prices as of 2026-10-06
7 models are higher-scoring or cheaper, with neither dimension worse.
Of the 144 models carrying both an independent score and a published price at the same delivery mode, 23 score at least as high as GLM 5V Turbo and cost no more under at least one listed workload, with at least one of those dimensions improved. 7 match or beat its recorded context, maximum output, input modes, tool use and extended reasoning. 16 have a recorded capability loss, named on every row.
Dominance is not a property of a model. It is a property of a model, a capability lens and a workload, and all three are named on every row. Scores are LMArena Elo, used under CC BY 4.0 from the official dataset; prices are blended per million tokens. A higher score is not a drop-in replacement.
This page is built only while a candidate improves score or price without worsening the other under a listed workload. When that comparison no longer holds, it is not generated.
Where it holds
| Workload | GLM 5V Turbo $/M | Recorded capabilities preserved | Recorded capability losses |
|---|---|---|---|
| Balanced | $1.90 | 4 | 16 |
| Summarise | $1.07 | 4 | 15 |
| Chat | $2.03 | 4 | 15 |
| Code gen | $2.80 | 4 | 16 |
| Agentic | $1.05 | 7 | 15 |
Workload mixes are defined on the methodology page. Cached input is priced at the cached rate, and reasoning tokens at the worse of the reasoning and output rates.
What you would be replacing
| Intelligence | 1437.2 |
|---|---|
| Context window | 202K |
| Max output | 131K |
| Input modes | image, text, video |
| Tool use | yes |
| Extended reasoning | yes |
Preserving recorded capabilities requires matching or beating these fields. Full record for GLM 5V Turbo, or check GLM 5V Turbo against the whole catalogue.
Recorded capabilities preserved 7
Each option has a higher score or a lower price, with neither dimension worse under the listed workloads. It matches or beats GLM 5V Turbo on recorded context, maximum output, input modes, tool use and extended reasoning.
| # | Model | Intelligence | $/M | Holds under |
|---|---|---|---|---|
| 1 | MiMo-V2.6-Pro Xiaomi | 1491 +53.8 | $0.540 |
|
| 2 | GLM 5.3 Flash Z.ai | 1469.6 +32.4 | $0.238 |
|
| 3 | MiMo-V2.6-Flash Xiaomi | 1456.4 +19.2 | $0.175 |
|
| 4 | Qwen3.8 27B Qwen | 1440.7 tie | $0.562 |
|
| 5 | Muse Spark 1.3 Meta | 1489.9 +52.7 | $1.05 agentic |
|
| 6 | Muse Spark 1.2 Meta | 1483.2 +46 | $1.05 agentic |
|
| 7 | Muse Spark 1.1 Meta | 1479.2 +42 | $1.05 agentic |
|
Alternatives with recorded capability losses 16
These improve score or price without worsening the other under the listed workloads, but reduce at least one recorded capability. Read the last column before switching.
| Model | Intelligence | $/M | Holds under | Recorded capability loss |
|---|---|---|---|---|
| Gemini 3.6 Flash Google | 1479.5 +42.3 | $1.50 |
|
|
| GLM 5.3 Z.ai | 1471.4 +34.2 | $1.00 |
|
|
| GLM 5.2 Z.ai | 1470.4 +33.2 | $1.12 |
|
|
| MiMo-V2.5-Pro Xiaomi | 1465 +27.8 | $0.544 |
|
|
| DeepSeek V4.1 Flash DeepSeek | 1462.5 +25.3 | $0.182 |
|
|
| GLM 5.1 Z.ai | 1461.5 +24.3 | $1.83 |
|
|
| Qwen3.7 Plus Qwen | 1454.6 +17.4 | $0.560 |
|
|
| Kimi K2.6 Moonshot AI | 1455.5 +18.3 | $0.961 |
|
|
| Gemma 4 31B Google | 1443.4 tie | $0.205 |
|
|
| GLM 5 Z.ai | 1446.3 tie | $1.09 |
|
|
| Hy3 Tencent | 1440.7 tie | $0.231 |
|
|
| Kimi K2.5 Moonshot AI | 1445.2 tie | $1.20 |
|
|
| DeepSeek V4 Pro 0423 DeepSeek | 1445.2 tie | $1.21 |
|
|
| GLM 4.6 Z.ai | 1439.9 tie | $0.760 |
|
|
| Qwen3.5 397B A17B Qwen | 1438 tie | $0.878 |
|
|
| Inkling Thinking Machines | 1441.8 tie | $1.73 |
|
|
What this compares, and what it leaves out
- Quality is LMArena Elo, used under CC BY 4.0 from the official dataset. The 95% confidence interval on a difference between two scores is about ±10.47 points, so a gap smaller than that is marked tie rather than an improvement — see significance bands.
- 204 further models at this delivery mode carry a price but no independent score. They are absent from the comparison in both directions — unrated is not a zero, and an unmeasured model is neither an alternative nor a worse buy.
- Retired models are never offered as an alternative, and a model only competes against its own delivery mode: batch trades latency for price, so it is not a like-for-like swap.
- Nothing here measures latency, throughput, rate limits or how a model behaves on your prompts. Two models with the same index score are not interchangeable.
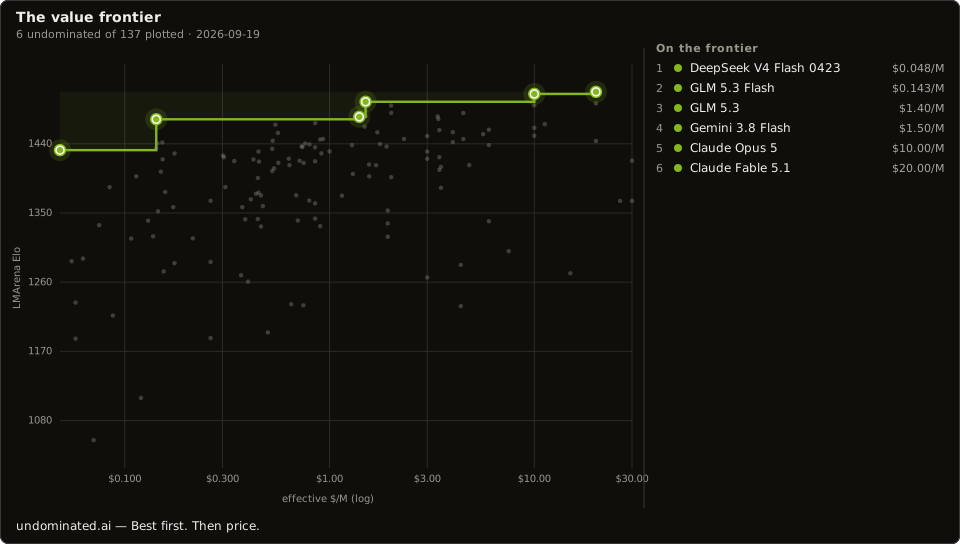
- Models with no higher-scoring or cheaper alternative that is no worse on the other axis are on the value frontier. Models with such an alternative are listed here.