
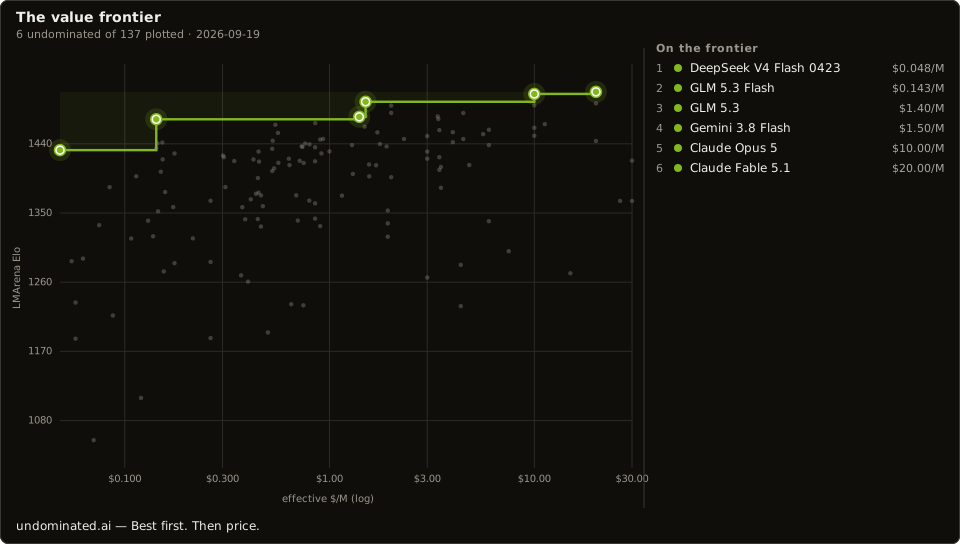
MODEL PROOF
Grok 4.6
BETTER VALUE OPTION
A stored alternative has an equal-or-higher measured score and an equal-or-lower price.
Base context tier shown; inspect the complete context ladder below.
Muse Spark 1.3 · Δ score 59.8 points · 33% lower measured price · $2.00 / 1M tokens
Gemini 3.8 Flash is a further stored option with these losses: 450K → 66K max output
- Independent LMArena score
- 1,429.9 ± 5.83 · 15,521 votes
- Context window
- 500K
- Maximum output
- 450K
- Input modalities
- text, image, file
- Output modalities
- text
- Published input price
- $2.00 / 1M tokens
- Published output price
- $6.00 / 1M tokens
- Pricing kind
- fixed
- Context tiers
- Tiered by context
Inspect complete billing conditions and endpoint terms below.
Every price dimension · USD per million tokens
| Input | $2.00/M |
|---|---|
| Output | $6.00/M |
| Cached input | $0.500/M |
| Cache write | Unknown/M |
| Cache write 1h | Unknown/M |
| Reasoning | Unknown/M |
| Web search | $0.005/call |
The headline rate does not apply to a long-context workload.
Complete context ladder · 1 tier
| More than 200,000 tokens | $4.00/M in (2×) $12.00/M out $1.00/M cached input Unknown/M cache write |
|---|
Who sells it
The same weights, different shops. Cheapest is not like-for-like when serving precision differs.
5 provider offers · rates, limits and conditions
Rates are USD per million tokens. Endpoint terms can differ even when the quoted price and precision match. A listed parameter is a provider declaration, not a task-success test.
| Seller | Input | Output | Precision | Uptime (1d) |
|---|---|---|---|---|
| xAIxai/zdr Endpoint terms
| $2.00 | $6.00 | undeclared | 99.85% |
| xAIxai Endpoint terms
| $2.00 | $6.00 | undeclared | 99.57% |
| Amazon Bedrockamazon-bedrock/us-west-2 Endpoint terms
| $2.20 | $6.60 | undeclared | 100.00% |
| xAIxai/zdr/priority Endpoint terms
| $4.00 | $12.00 | undeclared | 99.72% |
| xAIxai/priority Endpoint terms
| $4.00 | $12.00 | undeclared | — |
Independent scores
| LMArena Elo | 1429.9high |
|---|
LMArena Elo under CC BY 4.0. Absence of another board is not a score of zero.
Best rankings by task
- androidnative #1of 35 1300
- htmlslides #3of 23 1253
- mobileapps #4of 40 1267
- asciiart #7of 61 1292
- fullstack #7of 41 1271
- webapps #9of 40 1255
- agenticgamedev #9of 24 1210
- gamedev #10of 107 1318
Capability
| Context window | 500K |
|---|---|
| Max output | 450K |
| Input modes | text, image, file |
| Tool use | yes |
| Reasoning | always on |
| Open weights | no |
Provenance
| Price source | openrouter.ai |
|---|---|
| Fetched | 2026-09-23 |
| Quality data | verified |
| Cross-checked | vendor page |
A published time-to-first-token figure for this model was implausible (44s) and has been withheld rather than displayed.
Our take
editorial — not a measurementGrok’s output rate and context tier make the workload mix important. Compare the current selected-tier cost and proof with other candidates. The suspect latency figure is withheld and cannot establish a speed advantage. Check the recorded context and output limits before migrating long-document work.
Strengths
- Tool use and reasoning effort are listed
- The accepted table exposes the context-tier boundary
Weaknesses
- Long prompts can select a different rate
- A missing batch quote does not establish a discount or the absence of a batch product
Reach for it when
- Output-heavy workload evaluations
- Tasks with measured prompt and output sizes
Avoid it if
- The required context exceeds the recorded limit
- Your decision depends on an unverified latency or batch-price claim
Sources: docs.x.ai
Grok 4.6 is a model from SpaceXAI with frontier performance on coding, knowledge work, and STEM. It is succeeded by [Grok 4.7](/x-ai/grok-4.7).
Questions this page answers
What does Grok 4.6 cost?
$2.00/M in, $6.00/M out in this catalogue, as of the fetch date on this page. That is the API row, not a subscription.
Does Grok 4.6 have an independent quality score?
Grok 4.6 has an LMArena score in this catalogue.
What beats Grok 4.6?
Muse Spark 1.3 has an equal-or-higher measured score and an equal-or-lower price.
Does this page use Artificial Analysis scores for Grok 4.6?
No. Artificial Analysis figures are not published here. Quality on this page is LMArena Elo where a score exists; otherwise the row is unrated.
MODEL MONUMENT
Save or share this proof
Badge
The verdict as one SVG, for a README or a docs page. It states this model's dominance status at the balanced workload on the LMArena lens, with the date it was computed, and it is rebuilt with the catalogue — so it changes when the verdict changes, including to one you would rather it did not.
[](https://undominated.ai/models/x-ai__grok-4.6/)<a href="https://undominated.ai/models/x-ai__grok-4.6/"><img src="https://undominated.ai/badge/x-ai__grok-4.6.svg" alt="Grok 4.6 — Undominated.ai dominance verdict" height="36"></a>Direct file: https://undominated.ai/badge/x-ai__grok-4.6.svg — a static SVG, written by scripts/build-badges.mjs on every build, so the copy you embed is never
older than the last deploy.
