
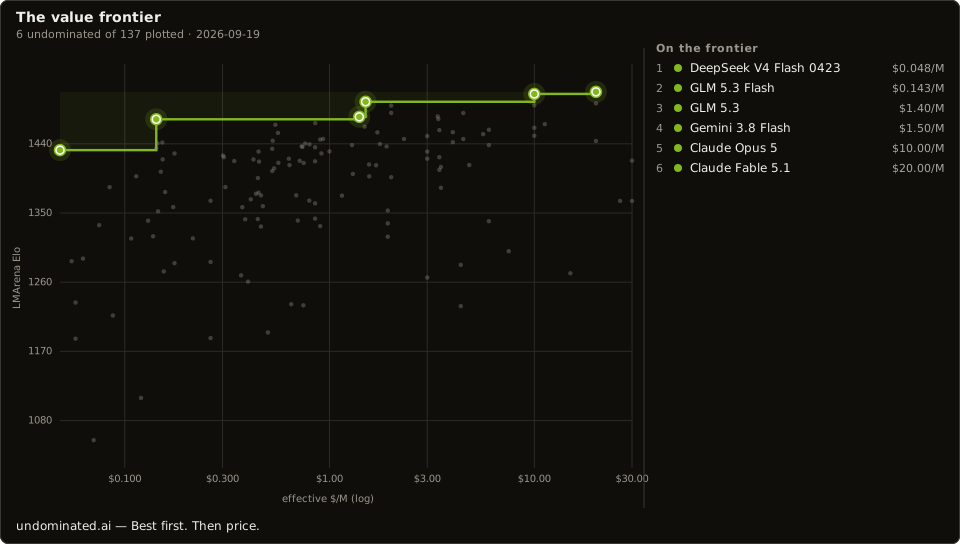
MODEL PROOF
GPT-5.6 Sol
TRADE-OFF
A stored alternative has an equal-or-higher score and an equal-or-lower price, with capability losses.
Base context tier shown; inspect the complete context ladder below.
Gemini 3.8 Flash · Δ score 39.6 points · 63% lower measured price
- 1.1M → 1M context
- 128K → 66K max output
- Independent LMArena score
- 1,455.1 ± 4.88 · 27,069 votes
- Context window
- 1.05M
- Maximum output
- 128K
- Input modalities
- file, image, text
- Output modalities
- text
- Published input price
- $2.00 / 1M tokens
- Published output price
- $10.00 / 1M tokens
- Pricing kind
- fixed
- Context tiers
- Tiered by context
Inspect complete billing conditions and endpoint terms below.
Every price dimension · USD per million tokens
| Input | $2.00/M |
|---|---|
| Output | $10.00/M |
| Cached input | $0.200/M |
| Cache write | $2.50/M |
| Cache write 1h | Unknown/M |
| Reasoning | Unknown/M |
| Web search | $0.01/call |
| Batch discount | 50% |
The headline rate does not apply to a long-context workload.
Complete context ladder · 1 tier
| More than 272,000 tokens | $4.00/M in (2×) $15.00/M out $0.400/M cached input $5.00/M cache write |
|---|
Who sells it
The same weights, different shops. Cheapest is not like-for-like when serving precision differs.
7 provider offers · rates, limits and conditions
Rates are USD per million tokens. Endpoint terms can differ even when the quoted price and precision match. A listed parameter is a provider declaration, not a task-success test.
| Seller | Input | Output | Precision | Uptime (1d) |
|---|---|---|---|---|
| OpenAIopenai/flex Endpoint terms
| $1.00 | $5.00 | undeclared | 98.67% |
| OpenAIopenai Endpoint terms
| $2.00 | $10.00 | undeclared | 99.99% |
| OpenAIopenai/fast Endpoint terms
| $4.00 | $20.00 | undeclared | 99.99% |
| Azureazure Endpoint terms
| $4.00 | $20.00 | undeclared | 99.84% |
| Azureazure/us Endpoint terms
| $4.40 | $22.00 | undeclared | 100.00% |
| Amazon Bedrockamazon-bedrock/us-east-1 Endpoint terms
| $4.40 | $22.00 | undeclared | 93.71% |
| Azureazure/eu Endpoint terms
| $4.40 | $22.00 | undeclared | 100.00% |
Independent scores
| LMArena Elo | 1455.1xhigh |
|---|
LMArena Elo under CC BY 4.0. Absence of another board is not a score of zero.
Capability
| Context window | 1.1M |
|---|---|
| Max output | 128K |
| Input modes | file, image, text |
| Tool use | yes |
| Reasoning | optional |
| Knowledge cutoff | 2026-02-16 |
| Open weights | no |
Provenance
| Price source | openrouter.ai |
|---|---|
| Fetched | 2026-09-23 |
| Quality data | verified |
| Cross-checked | vendor page |
A published time-to-first-token figure for this model was implausible (105s) and has been withheld rather than displayed.
Our take
editorial — not a measurementFor an existing OpenAI workflow, evaluate Sol using the prompt size and output mix you actually send. Its accepted rate table includes a context threshold, so a base-rate comparison is insufficient for long prompts. Use the current price table, proof and benchmark evidence for that comparison. A promotional minimum date does not establish an expiry or a successor price.
Strengths
- Selectable reasoning effort, tools and structured outputs are listed
- The price table exposes the context-tier boundary
Weaknesses
- Long prompts can select a different rate tier
- The suspect latency figure is withheld and does not support a speed comparison
- Confirm vendor promotional terms before forecasting future spend
Reach for it when
- Evaluation within an existing OpenAI tool stack
- Workloads whose prompt-size distribution is known
Avoid it if
- Your budget assumes the base rate for every prompt
- You need a latency guarantee without deployment measurements
Sources: developers.openai.com
GPT-5.6 Sol is the flagship model in OpenAI's GPT-5.6 series. It is suited for complex reasoning, coding, and agentic workflows, and is particularly strong at command-line and multi-step coding tasks...
Questions this page answers
What does GPT-5.6 Sol cost?
$2.00/M in, $10.00/M out in this catalogue, as of the fetch date on this page. That is the API row, not a subscription.
Does GPT-5.6 Sol have an independent quality score?
GPT-5.6 Sol has an LMArena score in this catalogue.
What beats GPT-5.6 Sol?
Gemini 3.8 Flash has an equal-or-higher measured score and an equal-or-lower price, with capability trade-offs.
Does this page use Artificial Analysis scores for GPT-5.6 Sol?
No. Artificial Analysis figures are not published here. Quality on this page is LMArena Elo where a score exists; otherwise the row is unrated.
MODEL MONUMENT
Save or share this proof
Badge
The verdict as one SVG, for a README or a docs page. It states this model's dominance status at the balanced workload on the LMArena lens, with the date it was computed, and it is rebuilt with the catalogue — so it changes when the verdict changes, including to one you would rather it did not.
[](https://undominated.ai/models/openai__gpt-5.6-sol/)<a href="https://undominated.ai/models/openai__gpt-5.6-sol/"><img src="https://undominated.ai/badge/openai__gpt-5.6-sol.svg" alt="GPT-5.6 Sol — Undominated.ai dominance verdict" height="36"></a>Direct file: https://undominated.ai/badge/openai__gpt-5.6-sol.svg — a static SVG, written by scripts/build-badges.mjs on every build, so the copy you embed is never
older than the last deploy.
